
 Ask Claude about this post
 Ask ChatGPT

A local model is a file you download once. After that the model runs on your own computer like Figma or Photoshop does.
You need no account and no internet connection. You pay nothing per token and nobody can switch the model off or replace it with a worse version.
In this guide I take you from zero to a model you use every day. You only need the terminal in the last step and that step is optional.
If you want to skip the manual route there is a Claude Code prompt at the end of this post that does the whole setup for you.
What I use my local model for
Honest expectation first: the results are okay but not groundbreaking. Cloud models are still clearly better today.
- Figma without the cloud: figma-cli controls Figma Desktop from your machine and works with a local model. Type "add my brand colours as variables" or "create 3 button components" and it shows up on the canvas. On my setup one action takes three to eight seconds plus the time Figma needs to draw it. Your design system and your file and the model never leave the laptop. That decides whether you can use AI on a client project at all.
- Copy in your own voice: This one pays for itself. The system prompt sits in the right hand panel and the model reads it before every message. Paste ten of your own posts in there and add "write like this". Every draft then starts in your voice. Mine also has rules like no em dashes and no "leverage" or "delve" and a local model follows them.
- Transcripts to drafts: I record a call or a talk and give the model the transcript. I get a structured draft back. This saves me a lot of time every week.
- Translation: Interface strings, a client email in another language or subtitles. It is fast and free so you can run a hundred of them.
- Simple websites and prototypes: The model writes the HTML and CSS for a landing page or a one page portfolio. You open the file in your browser.
- Boring text work: Rename 200 layers to one scheme, clean up a CSV, rewrite alt text for a folder of images or turn messy notes into a table.
- Anything you would never paste into a cloud tool: Contracts, salary talks, a brief under NDA or a medical letter. Whole industries are not allowed to send data to a third party API. A local model is the only way they get to use AI.
- Offline work: On flights, on trains and on bad wifi.
Where it fails: current events. A model only knows what happened before its training date and has no internet of its own. Exact maths is weak too. Very long documents hit a memory limit and not an intelligence limit.
What you gain and what it costs you
| You gain | It costs you |
|---|---|
| Privacy: nothing leaves your machine, so contracts and NDA briefs are fine | Some quality: top cloud models are smarter on hard reasoning. In everyday work you will not notice |
| No usage bill: after the download every question is free and the only cost is electricity | Heat and battery: a big model under load makes the fans spin and drains the battery |
| Offline: works on a plane or in a basement with bad wifi | Disk space: 8 to 24 GB per model |
| Stability: no deprecation email and no rate limit at the worst moment | Memory: the model sits in RAM while it is loaded and long documents need extra |
| Your own files: drop a document in and ask questions about it offline | No web access: it knows nothing about today unless you give it tools |
You do not have to choose. I keep my cloud subscription and let the local model take part of my routine work.
Step 1: Find out how much memory your Mac has
This is the only technical decision in the guide and it is all about memory.
You need an Apple Silicon Mac (M1 or newer) on macOS 14 or later. Intel Macs do not work. On Windows LM Studio asks for 16 GB RAM and a GPU with at least 4 GB VRAM (system requirements).
The B in Gemma 4 12B stands for billion parameters. Parameters are the internal dials the model learned during training. More parameters give you a better model and also a bigger file that needs more memory.
The rule is simple: the model file has to fit into your RAM and leave room for macOS and your other apps. Keep about a third of your memory free.
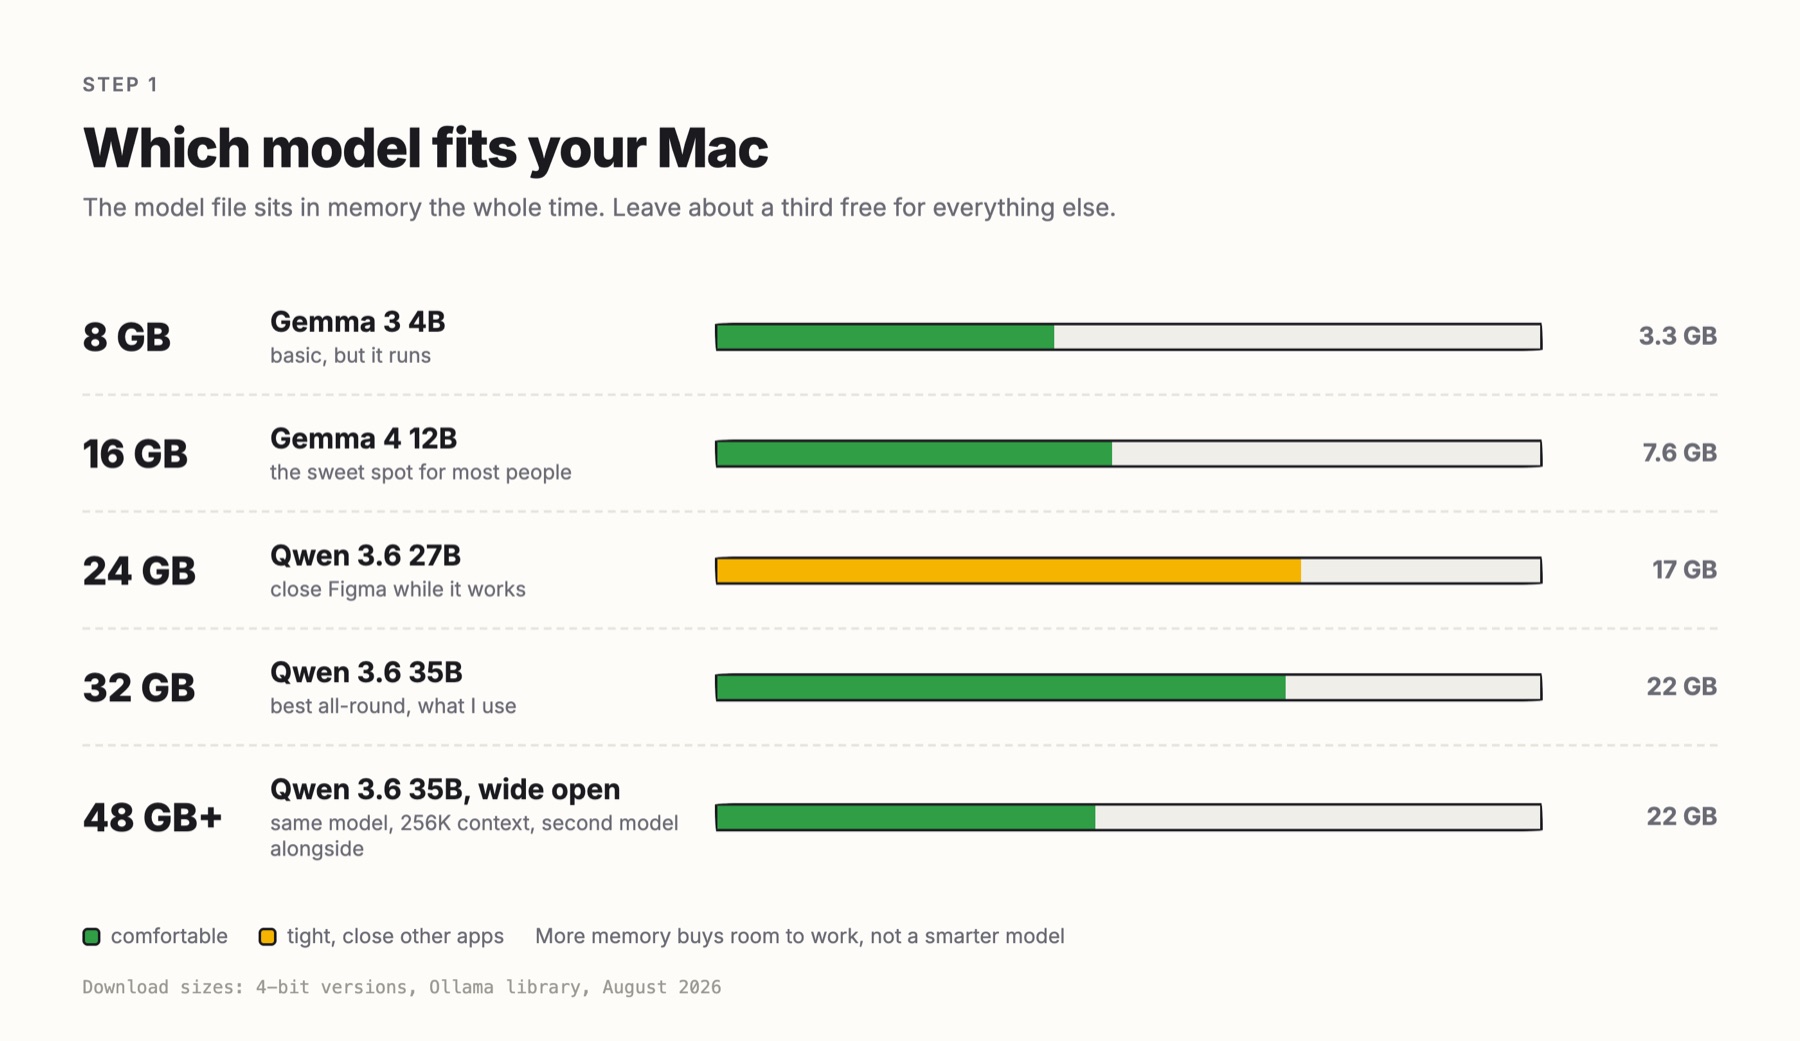
| Memory | Model and 4-bit download | Note |
|---|---|---|
| 8 GB | Gemma 3 4B: 3.3 GB | basic but it runs |
| 16 GB | Gemma 4 12B: 7.6 GB | the sweet spot for most people |
| 24 GB | Qwen 3.6 27B: 17 GB | close Figma while it works |
| 32 GB | Qwen 3.6 35B: 22 GB | best all-round and what I use |
| 48 GB and more | Qwen 3.6 35B: 22 GB | same model with a much bigger context window and a second small model next to it |
On 16 GB get Gemma 4 12B. It is small, writes clean text and handles a 256K context window. On 32 GB or more Qwen 3.6 35B is the best all-round model most people can run. I use it every day.
These names will change. New open models come out every month. DeepSeek, Llama and many others sit in the same library. I picked Gemma and Qwen because both families come in sizes a Mac can run and because I have used both. The memory maths stays the same. Learn that part and swap in whatever model is current when you read this.
Step 2: Install LM Studio
LM Studio is a normal Mac app with a model browser, a chat window and a settings panel.
Download it, drag it into Applications and open it. That is the install.
On Apple Silicon LM Studio runs models through MLX. That is Apple's own framework for the graphics chip. You do not have to set anything up. It just means models run noticeably faster on a Mac than the PC numbers you read online.
Step 3: Download your first model
Click Model Search in the narrow strip on the left. It is the last of the four icons and shows a magnifying glass over a little robot. A panel opens with a search field and a list of staff picks. Type the model name.
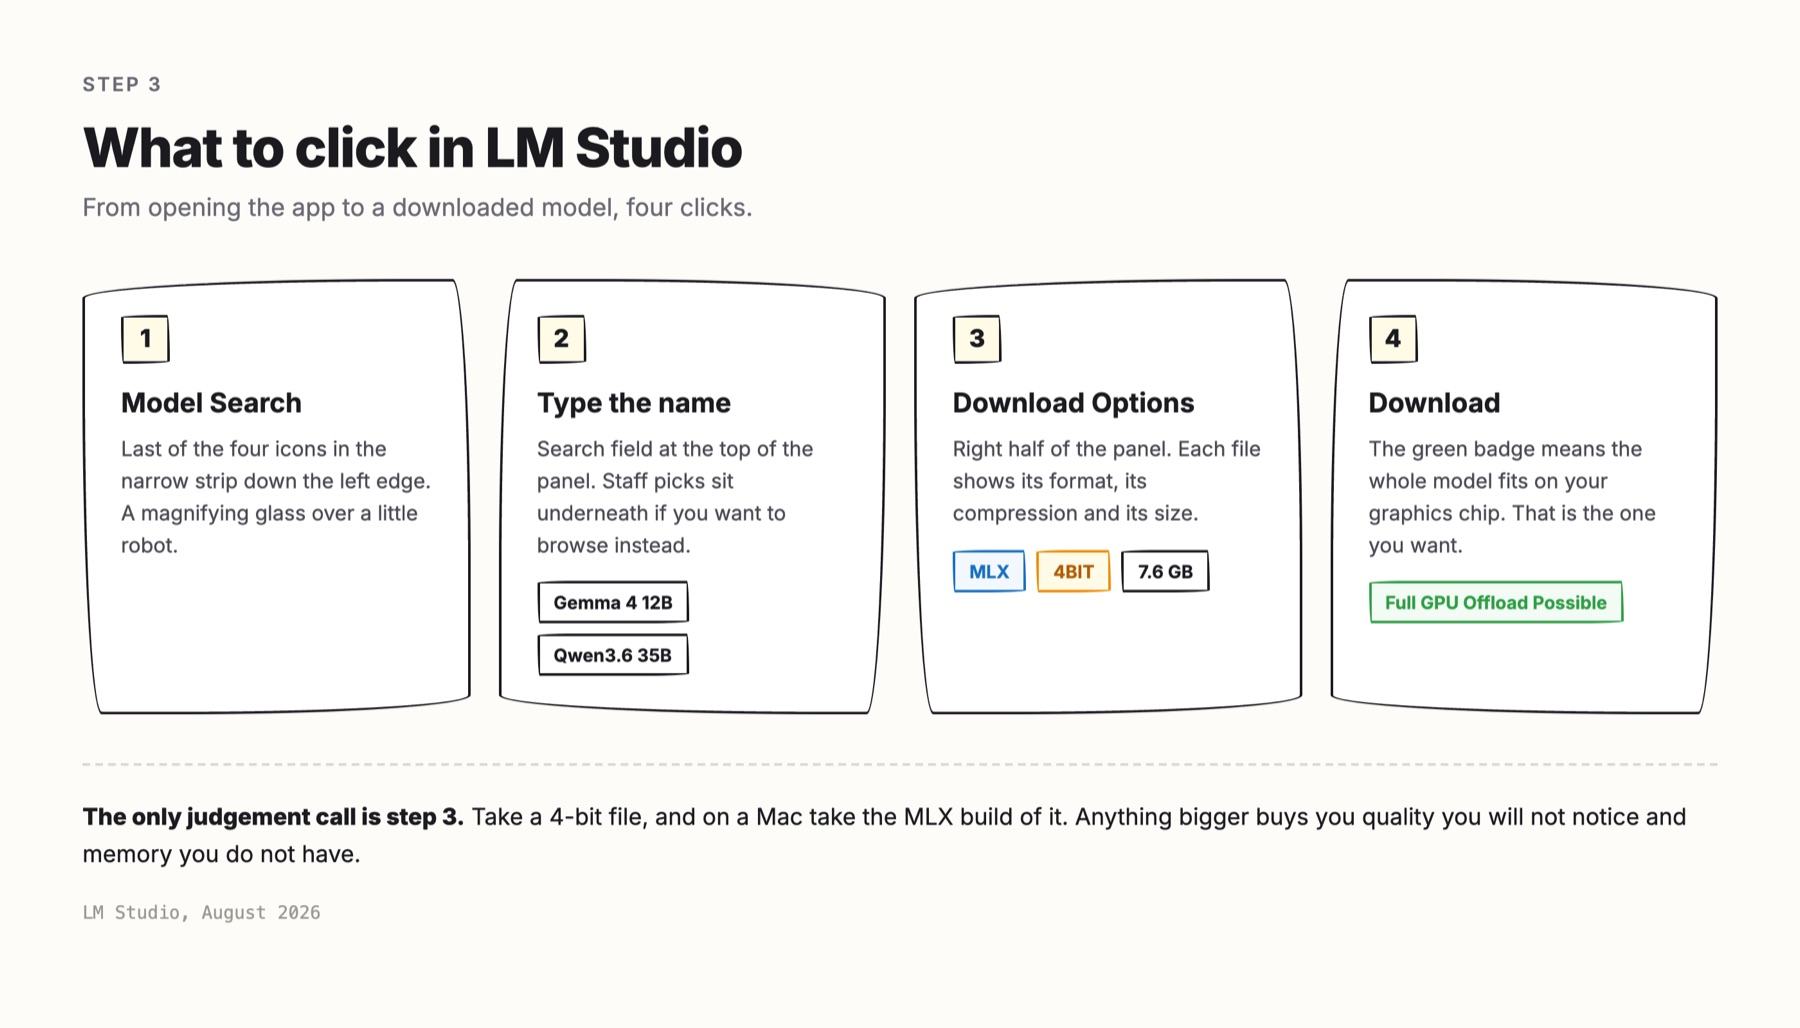
When you pick a model the right half of the panel shows its details. Under Download Options you see the same model several times in different sizes with names like Q4, Q4_K_M, Q8 and sometimes MLX.
That is compression and it is the one piece of jargon worth learning.
Think of the Figma export dialog. The same image leaves Figma as a 24 MB PNG or as a 2 MB JPEG at 80 percent and nobody in the review sees a difference. Model files work the same way. Gemma 3 12B is 24 GB uncompressed, 13 GB at Q8 and 8.1 GB at Q4. The quality gap between them is far smaller than the size gap.
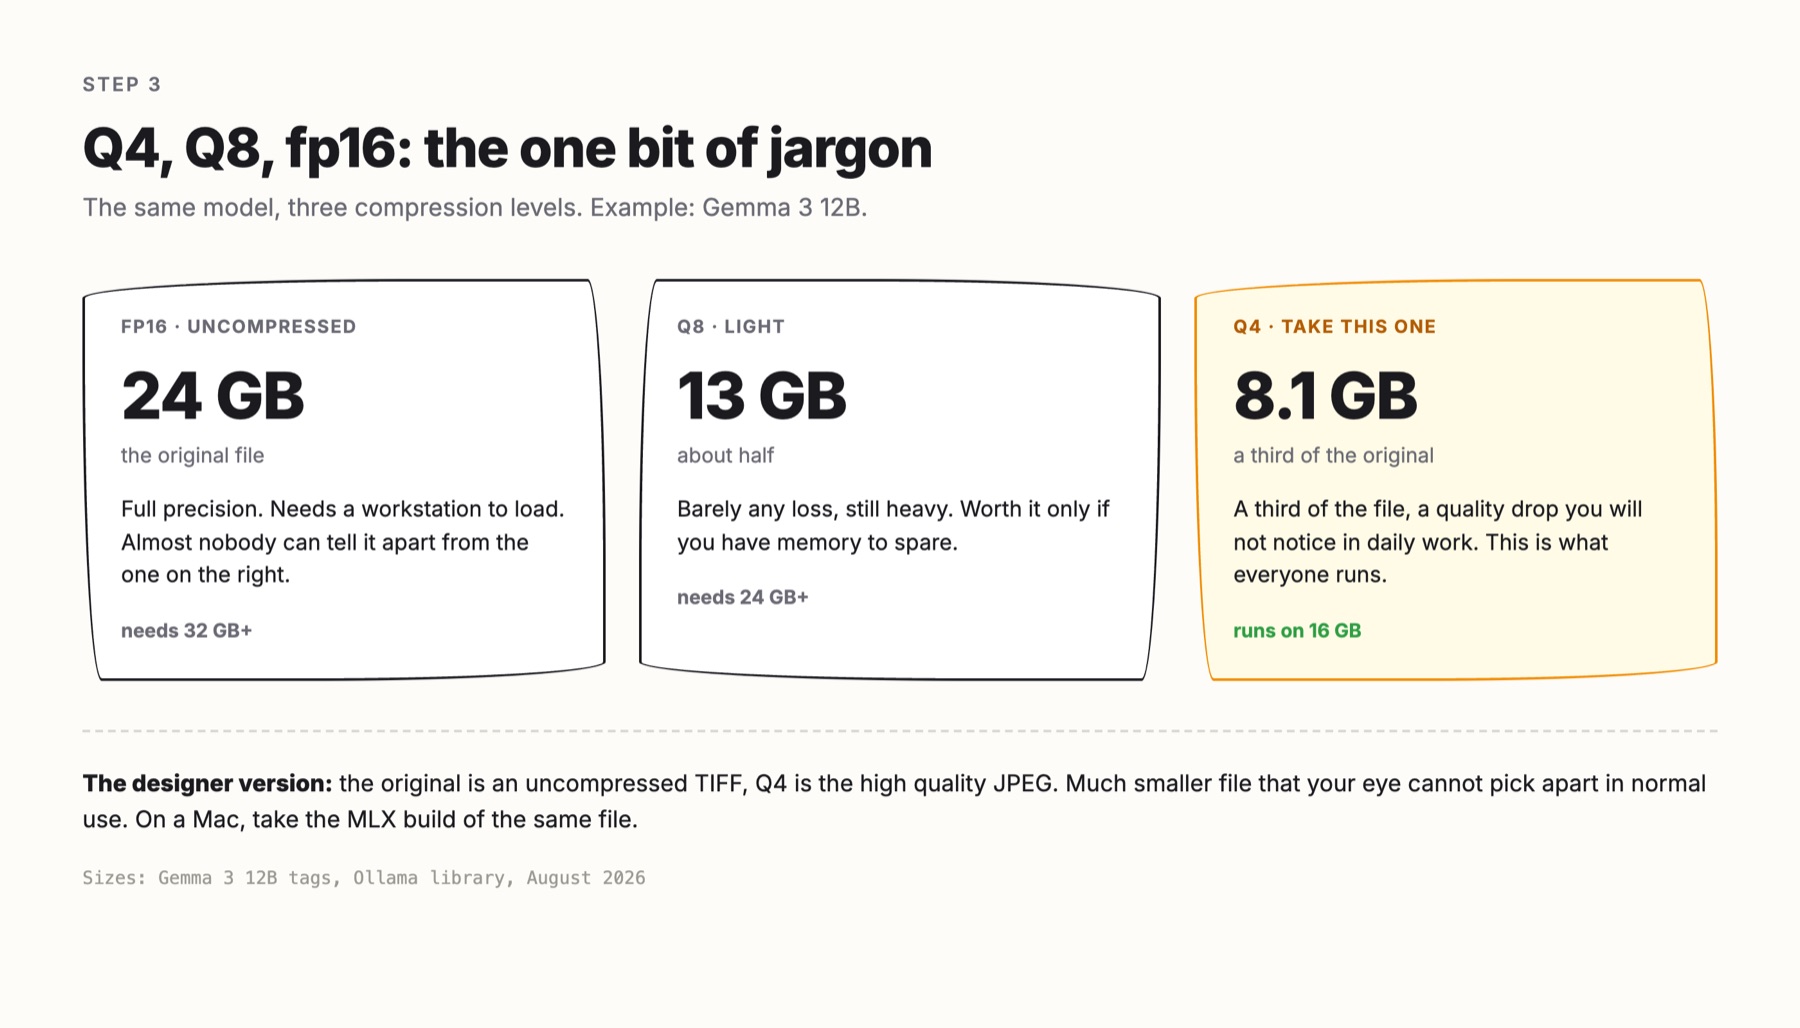
Why everybody takes 4-bit: you run out of memory long before you run out of quality. Gemma 3 12B at Q8 costs 13 GB. For four more gigabytes you can run Qwen 3.6 27B at 4-bit. That is more than twice the model. That is why 4-bit is the default and why LM Studio recommends 4-bit or higher.
MLX is not a compression level. It is Apple's own format of the same model and it is built for the graphics chip of an Apple Silicon Mac.
So take the 4-bit version and the MLX build of it if you see one.
Look for the green Full GPU Offload Possible badge next to the download. It means the whole model fits into the memory your graphics chip can reach and that is where the speed comes from. Without the badge the model still runs but slower.
The download sizes in this guide are for the 4-bit versions. On a 16 GB Mac Gemma 4 12B means a 7.6 GB download. Grab a coffee.
What to do with more memory than you need
On a 48 or 64 GB Mac a bigger file of the same model does not help. Spend the extra memory on these three things:
- A longer context window: that is what runs out in real work with a sixty page PDF, a full call transcript or a long chat. Going from 32K to 256K costs memory and nothing else.
- A bigger model if one exists: today the useful local range ends around 35B. That will change.
- Two models at once: a small fast one for quick rewrites and a big one for the important work without waiting for a swap.
On 64 GB you can run the largest model in this guide at its full 256K context and keep Figma open.
Step 4: Start your first chat
Go back to the chat tab and click Select a model to load at the top or press ⌘L. Pick your model and type a message. The first answer takes a few seconds longer because the model loads into memory.
Two settings in the right hand panel are worth changing:
- Context length: everything the model sees at once. That is your system prompt, the chat so far and any document you dropped in. It is counted in tokens. 32K is about 24,000 words or a fifty page document. When it is full the oldest part drops out. That is why a model forgets the start of a long chat. Context costs RAM and the default is usually low. I run 32K. If your Mac gets very slow lower this number first.
- Reasoning: some models think for 10 to 30 seconds before they answer. That is normal and not a crash. If it annoys you in everyday writing turn reasoning off in the same panel.
You can also drag a document into the chat and ask questions about it. That stays local too.
A token is about three quarters of an English word. "design system" is two tokens and "internationalisation" is four or five. Speed is counted in tokens per second and at 26 per second the text appears a little faster than you can read.
My own numbers on an M4 Max with Qwen 3.6 35B at 4-bit MLX and about 26 tokens per second:
| Task | Time |
|---|---|
| Short chat answer | 2 to 4 seconds |
| LinkedIn post | 4 to 8 seconds |
| Newsletter with subject and body | 8 to 15 seconds |
| Blog draft from a one hour call transcript | 60 to 120 seconds |
Step 5 (optional): The terminal route with Ollama
If you like the terminal, Ollama does the same job with one command per model and no app window.
ollama run gemma4:12b
This command downloads Gemma 4 12B and starts it.
This is also where a local model stops being a chat window and becomes a tool. I run LM Studio as a local server and point small scripts at it. One script writes LinkedIn posts, one writes newsletters and one turns a transcript into a blog draft. Each script is a text file with a system prompt inside.
Let Claude Code set it up for you
You can skip every step above. You need Claude Code for this because it can use your terminal and the Claude chat window cannot. Paste this prompt:
Set up a local LLM on this Mac for me. I am a designer, so explain what you are doing in plain language and do not ask me to run commands myself.

Step 1: Check the machine first. How much memory it has, which chip, which macOS version. Tell me what you found.

Step 2: Pick the model that fits. 8 GB: Gemma 3 4B. 16 GB: Gemma 4 12B. 24 GB: Qwen 3.6 27B. 32 GB and up: Qwen 3.6 35B. Always the 4-bit build, and the MLX build if there is one. Leave about a third of my memory free.

Step 3: Install LM Studio if it is not there yet, plus its command line tool.

Step 4: Download the model you picked. Tell me how big the download is before you start it.

Step 5: Load it with a 32K context window and start the local server.

Step 6: Prove it works. Ask it one question, show me the answer and the speed in tokens per second.

Step 7: Finish with three lines. Which model I now have, how to start it again after a reboot, how to stop it when the fans get loud.

If something fails, tell me what failed and what you would try next. Do not retry silently.
The order matters. Claude checks your Mac before it picks a model and cannot download one that does not fit. It installs the same things as the manual route: LM Studio and one model file.
How to pick models later
Model names change fast and most lists you find online are outdated. Two rules stay true.
Check the date of every list you read. That includes this one. I checked every model in this guide on Ollama in August 2026.
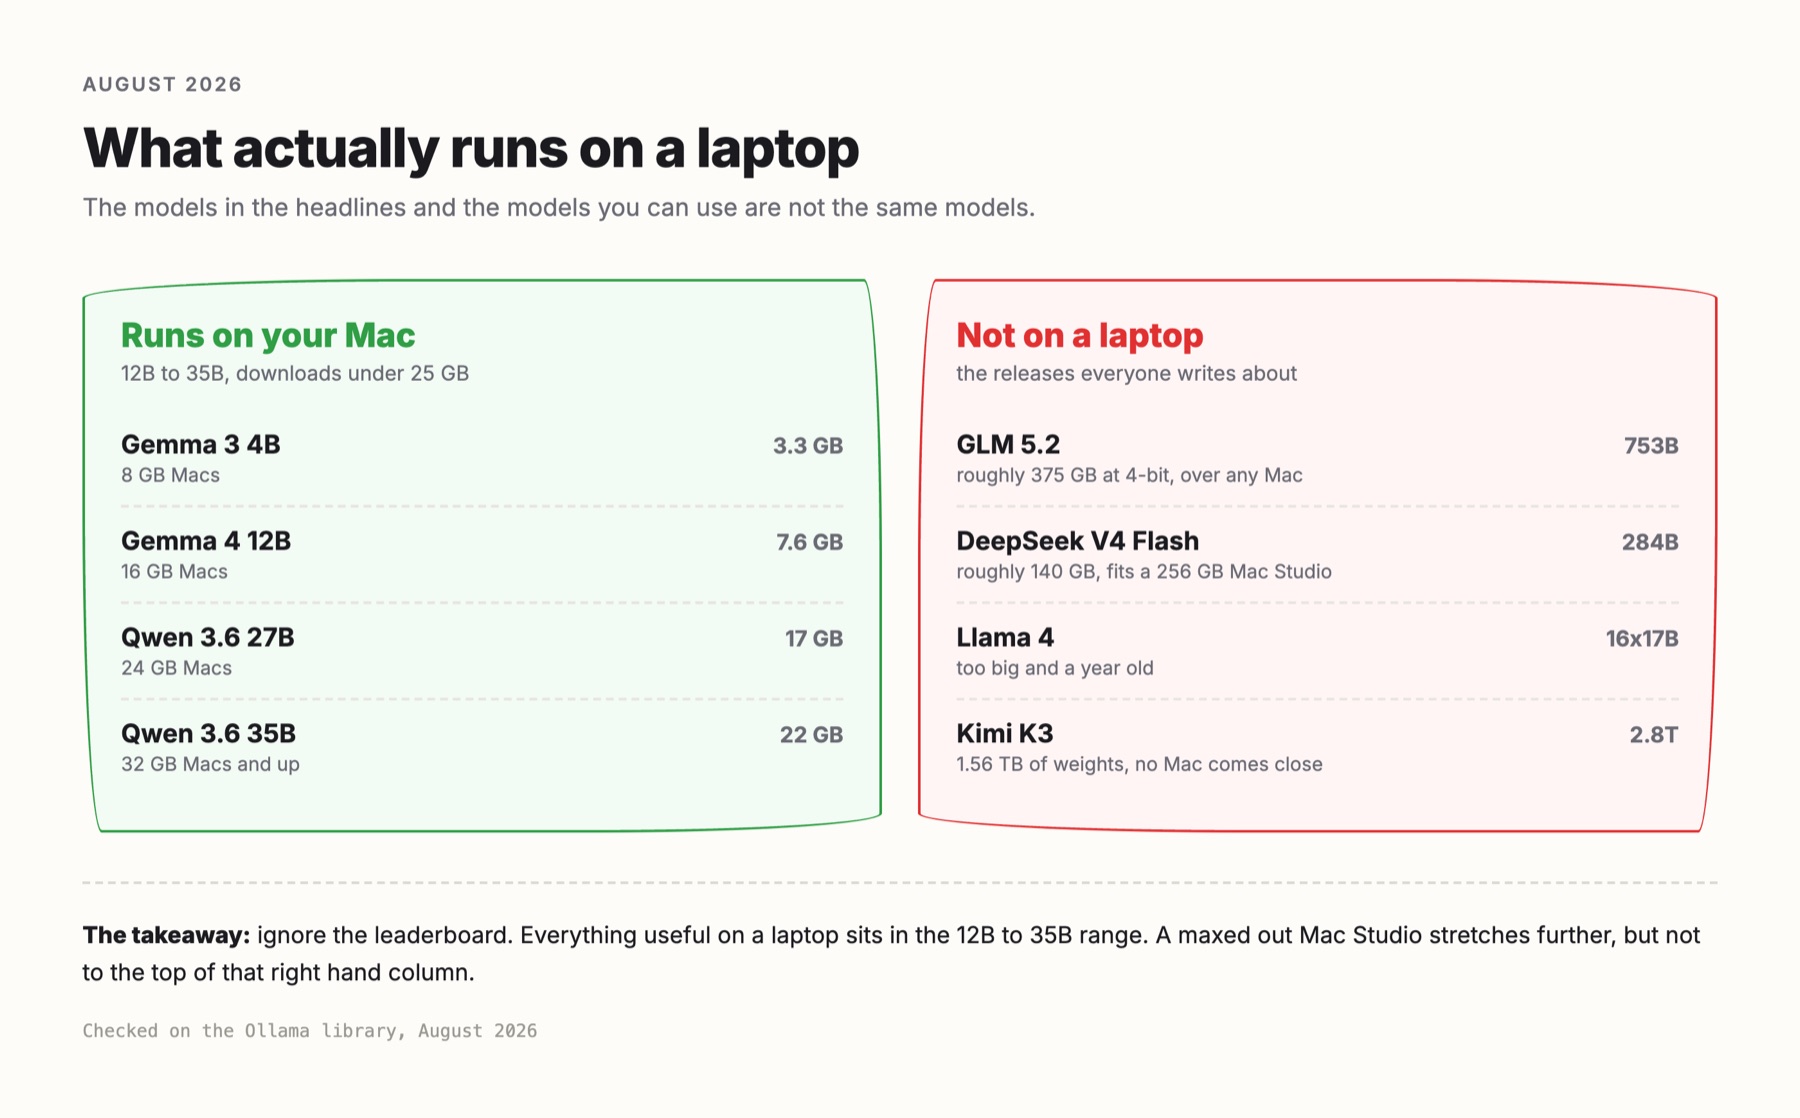
Ignore the headline releases. The models everyone writes about this summer have 300 billion parameters and more. They do not run on a laptop. The interesting local models sit between 12B and 35B. Llama is the name most people still think of first and it has not shipped a model in that size in a year.
Your checklist
- Download LM Studio
- In Model Search look for Gemma 4 12B on 16 GB or Qwen 3.6 35B on 32 GB and more
- Take the 4-bit MLX version
- Set the context length to 32K
- Paste ten of your own posts into the system prompt and ask for a draft
Stuck on one of the five? Ask in the Into Design Systems Slack.


